Friday, September 19, 2025

How to build Data Integrations from Oracle Fusion to Autonomous Data Warehouse using OCI-DI and BI Cloud Connector

In this blog, I'll walk through how to extract data from Oracle Fusion using BICC (Business Intelligence Cloud Connector) and interface it into Oracle Autonomous Data Warehouse (ADW) using OCI Data Integration Service (OCI-DI).

We’ll use a supplier example to demonstrate the process.


Step 1: Create a Custom Offering in BICC

The first step is to set up a custom offering in BICC using a Public View Object (PVO).

You can access to the Oracle Fusion BICC console typically by navigating to https://<your-fusion-host>/biacm


What is a PVO?

A PVO is a Public View Object that provides a structured way to access base tables in Oracle Fusion Cloud. Some PVOs are extract PVOs, which are optimized for extraction. Non-extract PVOs may run larger queries in the background.


Example:

We created a custom offering using the Supplier PVO.


Storage Configuration:

Storage Configuration in BICC lets us connect BICC with OCI Object Storage so that the data extracts can be staged over the Buckets in the object storage.

In OCI, create or identify the Object Storage bucket and note the following:
Bucket name
Namespace
Tenancy OCID
Region / host URL
User OCID for the OCI user you'll authenticate as.

The OCI user must be able to read/write the bucket (appropriate IAM policies must be in place).

In BICC, navigate to Configure External Storage -> OCI Object Storage Connection


Fill-in the fields as required:

Name: Friendly name for this connection.

Host: Object Storage endpoint URL for the region.
Example: https://objectstorage.<region>.oraclecloud.com
(e.g. https://objectstorage.us-ashburn-1.oraclecloud.com).

Tenancy OCID: Paste the tenancy OCID you copied earlier. 

User OCID: Paste the OCI user OCID for the user that will be used to access the bucket. 

Namespace: The object storage namespace for your tenancy. 

Bucket: The bucket name you created/are using.


In the OCI API Signing Key area click Generate API Signing Key. BICC generates a key and shows the Fingerprint.

Click Export Public Key. This will download a .pem file (public key).


BICC keeps the private key for signing. You will paste the public key into the OCI Console for the user specified above.


In OCI Console, add the exported public key to the OCI user.

- Navigate to OCI Console -> Identity & Security -> Users -> Select the user (the same OCID you entered above).

- Under API Keys, click Add Public Key -> provide the .pem file exported from BICC. Click Add.

The fingerprint shown in OCI should match the fingerprint shown in the BICC UI.


Now, navigate back to BICC console -> OCI Object Storage Connection

Under Verification, click Test Connection.

If all goes well, the test would succeed

Save the connection and close.

At this stage we have completed all the required configurations in Oracle Fusion BI Cloud Connector (BICC).


Step 2: OCI Data Integration

Oracle OCI provides a cloud-native service named Data Integration to extract, transform, and load data.


- Navigate to OCI Data Integration.


- Go go Workspaces -> Create a workspace (e.g. BICC-ADW)


- Define data assets (connectors) for the source and target:

1. BICC Data Asset (Source)


- Type: Oracle Fusion Applications

- Oracle fusion applications host: Provide the host of your Fusion pod

- Default connection type: Oracle BI Cloud Connector

- Provide the Fusion username and password


2. ADW Data Asset (Target)


- Type: Oracle Autonomous Data Warehouse

- Upload Wallet: Upload the database wallet pertaining to your ADW

- Wallet Password: Provide if applicable

- Provide database username and password

- Select the desired TNS alias from the available list


3. Object Storage Data Asset (for staging the files intermediately)


- Type: OCI Object Storage

- Namespace: Provide Namespace in which your bucket resides

- OCI Region: Select the applicable region as per your tenancy


Once above steps are completed, we should have below data assets configured:


Step 3: Build a Data Flow


Once data assets are ready, create a project in Data Integration and define data flows:

Project:


Create a new data flow for our extracting Supplier data from BICC offering we created earlier.


1. Source Node:

    Use the BICC data asset.

    Select the custom offering as the schema.

    Choose the PVO you want to extract.

    Set extract strategy to incremental to pull only new or updated records.

    Select “Manage” to let the OCI-DI track the last run date automatically.


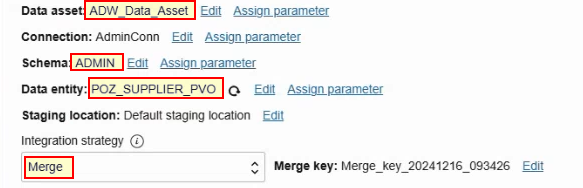
2. Target Node:


    Use the ADW data asset.

    Specify the schema and target table.

    Set the merge strategy: new rows are inserted, updated rows are updated.

    Define merge keys (unique identifiers for records).


3. Filtering:

Apply a filter based on the system variable ${SYS.LAST_LOAD_DATE}, ensuring only delta data is extracted.

This approach allows data to be pulled incrementally from BICC and merged into ADW seamlessly.


Step 4: Encapsulate Data Flow in a Task


Each data flow is wrapped in a task for execution.


Step 5: Build a Pipeline


- We can organize multiple tasks using a pipeline.

- Create a Pipeline and use the Integration Task as one of the nodes between Start and End.

- We can integrate many such nodes in Serial or Parallel manner in a Pipeline, based on the requirements.

- We can also apply conditional logic, expressions, or SQL tasks.

- Pipelines allow complex orchestration similar to Oracle Integration Cloud (OIC) integrations.


Step 6: Encapsulate Pipeline in a Task and Publish the tasks to Application


- Similar to the Data Flow, even Pipeline needs to be wrapped in a task for execution.

- Once done, Publish the Tasks to the Application


Step 7: Run the Pipeline


- Let's first create a new supplier (Test Supplier) in Fusion so that we can validate if this records gets interfaced to ADW once we run the Pipeline.


- Navigate to the OCI-DI Application

- Go to Tasks -> Locate the Pipeline Task -> Click the context menu -> Run


- OCI-DI Pipeline run can be tracked under Runs section


- Behind the scenes, OCI-DI automatically submits an ESS job to extract data from BICC.


- Data is extracted and stored as a CSV in OCI Object Storage.


- Pipeline completes Successfully and under the Integration Task node, we can see it extracted 8 new records from Fusion over to ADW


Step 8: Verify the data

- As we can see, the newly created supplier (Test Supplier) has been successfully interfaced over in ADW


Conclusion:

OCI Data Integration (OCI-DI) provides a powerful, cloud-native way to move data from Oracle Fusion BICC into Autonomous Data Warehouse (ADW) seamlessly. By leveraging features like incremental extraction, managed load strategies, and merge operations, organizations can avoid heavy full-load extractions and instead synchronize only the data that has changed since the last run. This not only improves performance and reduces costs but also ensures that ADW always reflects the latest state of Fusion data with minimal lag.

With its intuitive workspace, reusable data assets, and orchestration pipelines, OCI Data Integration enables teams to design and automate robust data flows across multiple PVOs and Fusion modules. Combined with BICC’s ability to export data securely to OCI Object Storage, the solution establishes an efficient and scalable data integration pattern that supports daily refreshes, near-real-time reporting, and downstream analytics with confidence.


Share:

Tuesday, August 19, 2025

How to use Oracle SQL Developer extension in Visual Studio Code

In today’s fast-paced development environment, productivity often depends on having the right tools in a single, seamless workspace. For database developers and administrators working with Oracle, switching between multiple applications to write queries, manage schemas, and debug can feel both time-consuming and disruptive. That’s where Visual Studio Code (VS Code), with its lightweight design and rich extension ecosystem, becomes a powerful ally.

The Oracle SQL Developer extension for Visual Studio Code (VS Code) is part of the Oracle Developer Tools for Visual Studio Code. It provides functionality for working with Oracle databases, similar to what one would expect from Oracle SQL Developer, but directly within VS Code.


Let's see how you can set up and use the Oracle SQL Developer extension from within Visual Studio Code.


- Click on Extensions option in the left pane


- This will bring Extensions Marketplace. Let's search for 'oracle sql developer' here.


- Click on the search results and it should open a new tab on the right side for 'Oracle SQL Developer Extension for VSCode'


- Let's click Install to install the extension.

- Installation usually takes less than a minute. Once installed, we should be able to see SQL Developer option in the left pane.


- Once we click on it, we should be able to see SQL Developer Navigation pane where we will be given an option to create a new database connection. Click on 'Create Connection'


- Let's create a new database connection. I'm going to connect to my ADW database that has been provisioned in OCI.

Enter Connection Name, Username/Password, Connection Type is going to be Cloud Wallet in my use case, but it can be set to Basic by providing the Host, Port etc. details as well.
I'm going to select the Wallet file I obtained from my ADW console in OCI.
In the end, we will Test the connection and Save it.


- Once done, we will see our connection in left pane. Let's right click and Connect.


- Once connected, we can expand various sections such as Tables, Views, Packages etc. to see all our existing database components. This is very similar to what we see in the SQL Developer tool.


- Let's open the Invoice table and we'll be able to see the details in a new tab on the right side. We can navigate through various sections such as Columns, Data, Grants, Indexes etc. very similar to how we can access them in SQL Developer tool.


- Let's go to data tab and insert a new record and fill in the values in respective columns. As we can see here, it automatically builds an Insert statement using our data and issues a commit implicitly.


- We can utilize additional tabs such as Dependencies where we will be able to see the dependent objects which are using the Invoice table. As we can see Invoice_Details_V view references the Invoice table, hence it's listed here.


- Similarly, we can access various code units such as Packages, Procedures, Functions etc. from the left pane. Here, we can see it shows us Package definition as well as Package Body details along with the sub-procedures under the packages.


- If we click on one of the procedures from within the Package then it will open the source code on the right side.


- Let's modify the sample code to add a test line and click Compile. This should recompile the package with our changes.


- Now, let's see how we can access the SQL CL terminal from within the VS Code.

- Navigate to Terminal tab. By default, it should show the PowerShell prompt like this.


- Let's right click on our database connection (ADW in this case) and select Open SQLcl option from the dropdown.


- It should connect to the database server in a new session and present us the good old SQL prompt.


- This is our typical SQL prompt where we can issue any SQL commands the way we would normally do on the traditional SQL prompt.


Conclusion:

As we can see, with the Oracle SQL Developer extension, we can work on our Oracle database directly from within VS Code IDE, without switching to a separate tool like Oracle SQL Developer or any other database management tool.

We get all the features of VS Code, such as syntax highlighting, code formatting, and version control integration, along with Oracle-specific features that provide us SQL, PLSQL support, Database exploration and management and rich debugging and testing capabilities.

By using the Oracle SQL Developer extension in Visual Studio Code, developers can significantly improve productivity and streamline their Oracle database development process, all within a single, powerful, and lightweight editor.


Share:

Monday, August 11, 2025

How to enable OCI Object Storage Buckets over SFTP using S3 Compatibility API and SFTPGo

Managing file transfers securely and efficiently is a critical requirement for many organizations, especially when integrating cloud storage into existing workflows. When it comes to Oracle Cloud Infrastructure (OCI), the Object Storage service is widely used for its durability, scalability. It's a internet-scale, high-performance storage platform offered by OCI which is scalable, flexible and offers greater data durability and resiliency.

However, many applications and legacy systems still rely on SFTP for file transfers. In such cases it gets tricky to get the data files transferred between such legacy systems and the OCI cloud platform.

By combining OCI Object Storage with S3-compatible endpoints and a lightweight, open-source tool like SFTPGo, we can seamlessly enable SFTP access to our OCI Object Storage buckets without restructuring existing processes. 

This article will explain step by step process on how to configure OCI Object Storage over SFTP using the S3 Compatibility API and SFTPGo, enabling secure, familiar file transfer workflows in a modern cloud environment.


High level steps
:

1. Create Bucket and Enable S3 compatible API

2. Generate Client Secret keys

3. Provision SFTPGo on OCI instance

4. SFTPGo configurations

5. Test the OCI bucket connectivity over SFTP


Let's dive in.


1. Create Bucket and Enable S3 compatible API

- Navigate to the Tenancy details 


- Once on Tenancy details page, note down the Compartment listed under Amazon S3 Compatibility API designated compartment as well as the Namespace of the Object Storage


If you wish to change the Amazon S3 compatible compartment, then you can do so by clicking 'Edit object storage settings' button and changing the S3 compatible compartment


- Let's create a new bucket in the above mentioned Compartment, as shown below. Let's name it sftpbucket


- Now that we've created a bucket under S3 compatible compartment, let's move on to step 2.


2. Generate Client Secret keys

- Navigate to profile and go to the User details page


- Go to Token and Keys section


- Scroll down to Customer Secret Keys section and click Generate secret key


- Give a relevant name to the key like sftogo and click Generate

- At this stage, it will generate the key and also show you the Secret.

Make sure to note the Secret down as it won't be displayed again after this stage.

- Also, note down the newly generated Key 


3. Provision SFTPGo on OCI instance


- Navigate to Compute -> Instances


- Create a new instance (or you can use your existing instance)

- If you are creating a new instance then below references may help:


Placement: AD 1

Image: Oracle Linux 9

Shape: VM.Standard.A1.Flex

Shape build: Virtual machine, 1 core OCPU, 6 GB memory, 1 Gbps network bandwidth

- While provisioning new instance, you'll be given an option to generate Private-Public key pair. Download the Private key and store it on your machine.

- Once you enter the instance, navigate to Instance access section and note down the Public IP Address and username (usually opc)


- Open command prompt on your machine

- Run below command

ssh -i <private key file path on your machine> opc@<public IP address)


- This will let us in the new instance, and you should see the shell prompt similar to this


- Now let's run below commands in the given sequence:


Create the SFTPGo repository:

ARCH=`uname -m`

curl -sS https://ftp.osuosl.org/pub/sftpgo/yum/${ARCH}/sftpgo.repo | sudo tee /etc/yum.repos.d/sftpgo.repo


Reload the package database and install SFTPGo:

sudo yum update

sudo yum install sftpgo


- At this stage we are done installing SFTPGo on our instance.

- Now, let's start the SFTPGo service and enable it to start at system boot:


sudo systemctl start sftpgo

sudo systemctl enable sftpgo

At this stage, we've started the SFTPGo server on our OCI instance.


SFTPGo server runs on the Public IP address of our instance and at the port 8080


Let's make sure we open this port in our firewall config.


Run this command to see the current firewall config

sudo firewall-cmd --list-all


Run below commands to add the port 8080 to firewall config and reload it

sudo firewall-cmd --add-port=<port_number>/tcp --permanent

sudo firewall-cmd --reload


At this stage we have completed all the configurations in installting and enabling SFTPGo on our OCI instance.


4. SFTPGo configurations


- SFTPGo WebUI is accessible at this URL: http://<Public IP of your Instance>:8080/web/admin


- Let's go to this URL in Chrome browser


- We'll be presented to configure Admin account upon accessing this URL first time


- Setup the Admin user name and Password and Save.


- Let's login to WebAdmin as the admin


- Once we login as Admin, we should see below page:


- Let's create a sftp user that will be used to access our Object Storage bucket


- Click Add


- Let's name our user sftpgo_user and provide a strong password


- Scroll down to File system section and fill-in below details:


Storage: S3 (Compatible)


Bucket: Bucket name from OCI Object Storage obtained from Step 1


Region: Your OCI Region


Access Key and Access Secret: Obtained from Step 2


Optionally, you can mention Key Prefix if you want to restrict access to a particular folder in the bucket and not provide access to the whole bucket.

For example if your bucket has a folder named SFTPFiles and you want SFTP User to have access only to this folder then you can mention SFTPFiles/ in the Key Prefix.


Now, we need to enter S3 compatible endpoint of our namespace in which the bucket resides.

The syntax for compatible endpoint URL is:


https://{object-storage-namespace}.compat.objectstorage.{region}.oraclecloud.com


So your endpoint URL will look similar to this -


- Click Save to create the SFTP user


- Once created, the Admin can see the user and it's status on the Users page


- At this stage we've completed all the SFTPGO configurations


5. Test the OCI bucket connectivity over SFTP


- Let's login to WebClient as the sftpgo_user


-
On the Files page, we can either create a New Folder or Upload a new File


- Create a new folder names test


- Let's upload a test file as well


We will be able to see the new folder and the newly uploaded file on SFTPGo Web Client


- Now, let's navigate back to the OCI Object Storage bucket and see if these new objects are available there


As we can see, both the folder and the file are available on our bucket -


Conclusion:


By combining the power of OCI Object Storage with the flexibility of SFTPGo and the S3 Compatibility API, organizations can modernize their file transfer infrastructure without disrupting existing processes. This solution offers a secure, cost-effective, and scalable way to support SFTP workflows while taking full advantage of cloud storage. Whether you're migrating legacy systems or building hybrid environments, this approach bridges the gap between traditional file transfer needs and modern cloud capabilities.


Share: